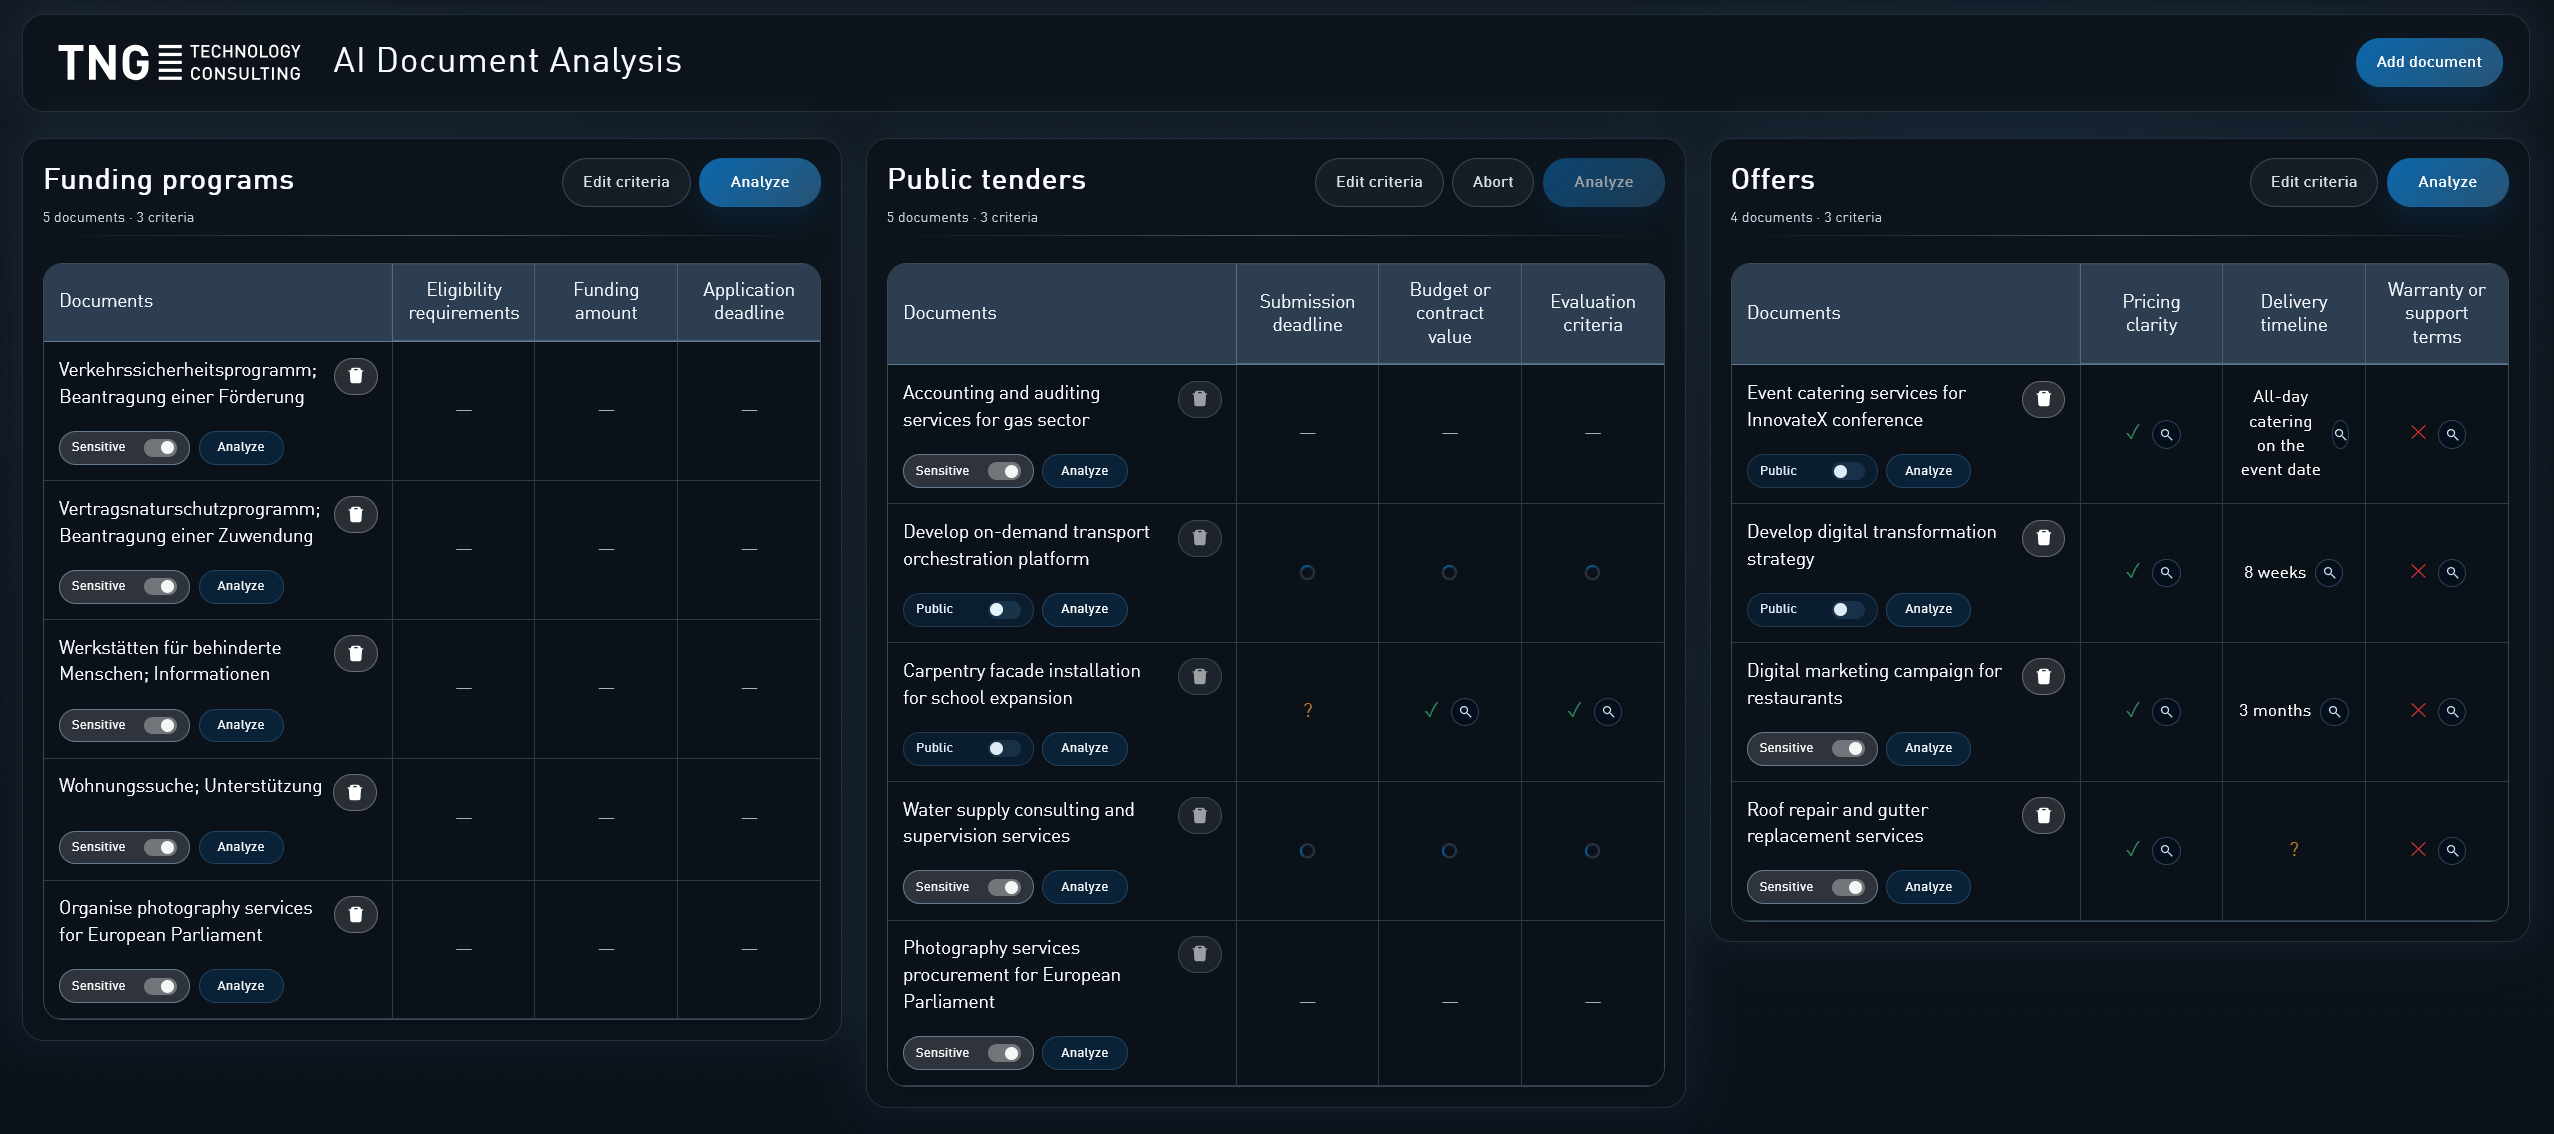
Agentic Document Analysis
Document-heavy workflows are everywhere in business. Common tasks include evaluating supplier bids, screening funding applications, reviewing contracts, and comparing research reports. What they share is a bottleneck: human readers can only process so much text before quality suffers or deadlines slip.
Large language models change this equation. They can read, extract, and compare information across large amounts of documents in minutes, applying consistent criteria every time. Our showcase makes this capability accessible: upload your documents, define what matters to you, and let the system do the groundwork. The output provides traceable reasoning for every judgement, allowing you to validate results and build trust in the process over time. When handling sensitive data, self-hosted models are used to eliminate the risk of data exposure.
The approach is domain-agnostic: whether you are comparing technical specifications, assessing regulatory compliance, or sifting through research literature, you simply define the criteria that matter for your context. No machine learning expertise is required to get started.